Topic

Reinforcement Learning

All digests tagged Reinforcement Learning

Suggested route

Topic journey

Move from earlier context through the available material to the newest signals. This route is a reading aid, not a difficulty ranking.

Start here

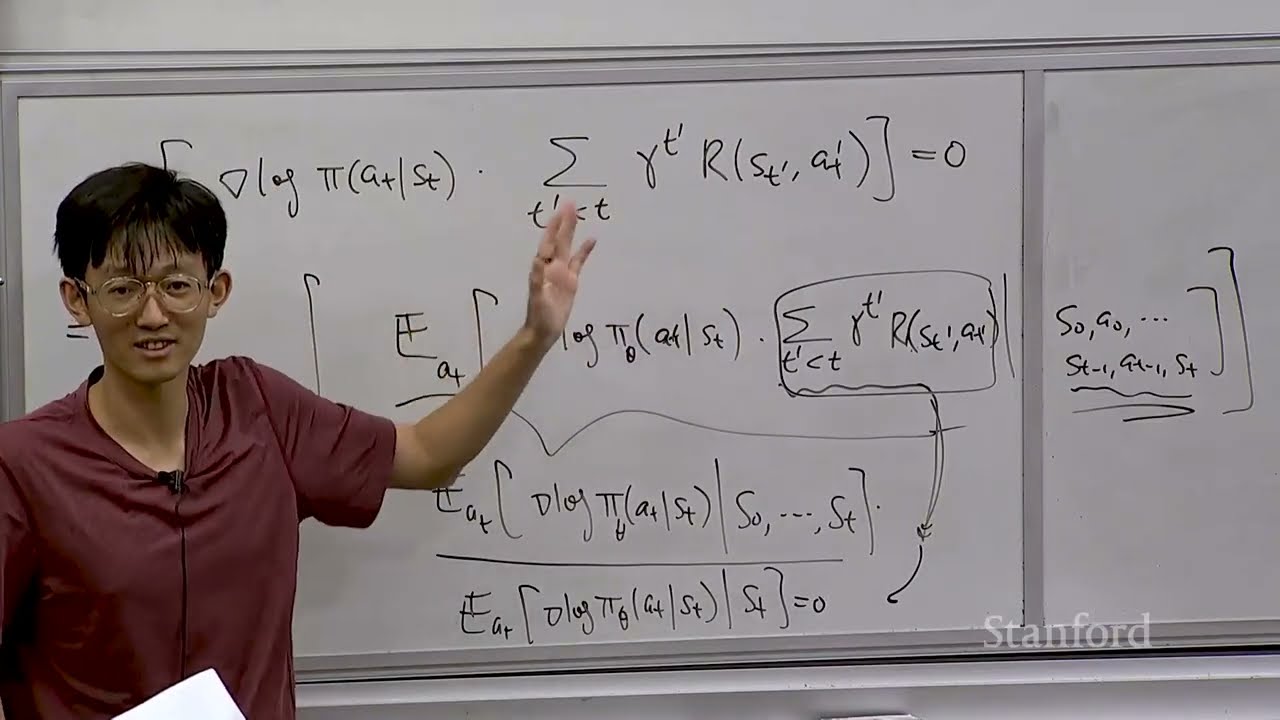
Stanford CS229 Machine Learning | Spring 2026 | Lecture 20: GMM (EM), PCA Jul 31, 2026 · 1:18:56 The lecture details advanced RL techniques for LLMs, covering Policy Gradient derivations and the stabilization mechanism of Proximal Policy Optimization (PPO). It shows how to model Chain-of-Thought prompting as an MDP problem.

Build context

What's Next After RLHF? — Diogo Almeida, TypeSafe AI Jul 31, 2026 · 18:05 Diogo Almeida argues that current LLMs, trained via RLHF, optimize for human preference rather than reliable automation. The next frontier requires optimizing AI for verifiable rewards and autonomous decision-making. Teaching AI to Find Real Vulnerabilities — David Brumley, Bugcrowd Aug 1, 2026 · 27:17 Brumley discusses designing RL environments for cybersecurity, arguing that true hacking requires a ladder of tasks from simple crashes to full arbitrary code execution. He introduces 'audit tasks' using deterministic graders to measure precision and recall across multiple vulnerabilities. Taking Reinforcement Learning Cross Datacenter — Nan Jiang, Modal Aug 10, 2026 · 19:50 To scale RL post-training cross datacenters, the synchronization unit must shift from massive full checkpoints (500 GB) to small 'lossless patches' representing only visible weight changes. This enables elastic rollout fleets.

Recent signals

Panel: When AI Feels Empathic - Richard Campbell, Martine Dowden, Michelle Frost & Tessel Haagen Oct 28, 2026 · 59:09 The panel debated the ethics of AI empathy, arguing that current models are optimized for maximum engagement, not utility. They stressed that robust 'guard rails' must address both technical vulnerabilities and societal misuse. An Eval for AI Scientists That Knows the Answer Key - Ian Quigley, Leash Bio Oct 26, 2026 · 16:34 Minos is a framework allowing scientific agents to explore pre-measured chemical environments for SAR optimization. It enables scalable, 'lab-in-the-loop' simulation for drug discovery. Hugging Face Journal Club: Score Centering Stabilizes Off-policy Reinforcement Learning Oct 26, 2026 · 32:26 Score Centering stabilizes Off-policy RL for LLMs by correcting the policy gradient loss when the training and inference policies mismatch. The method uses a Top-K approximation for efficient computation.

Browse view