Topic

Model Optimization

All digests tagged Model Optimization

Suggested route

Topic journey

Move from earlier context through the available material to the newest signals. This route is a reading aid, not a difficulty ranking.

Start here

Stanford CS329A Self-Improving AI Agents | Part 6 | Train Time Scaling/Scaling RL Aug 3, 2026 · 1:12:39 Dive into train-time scaling and RL techniques that enable self-improving AI agents. Learn how STaR, DeepSeekMath, and DAPO boost reasoning in LLMs using closed feedback loops.

Build context

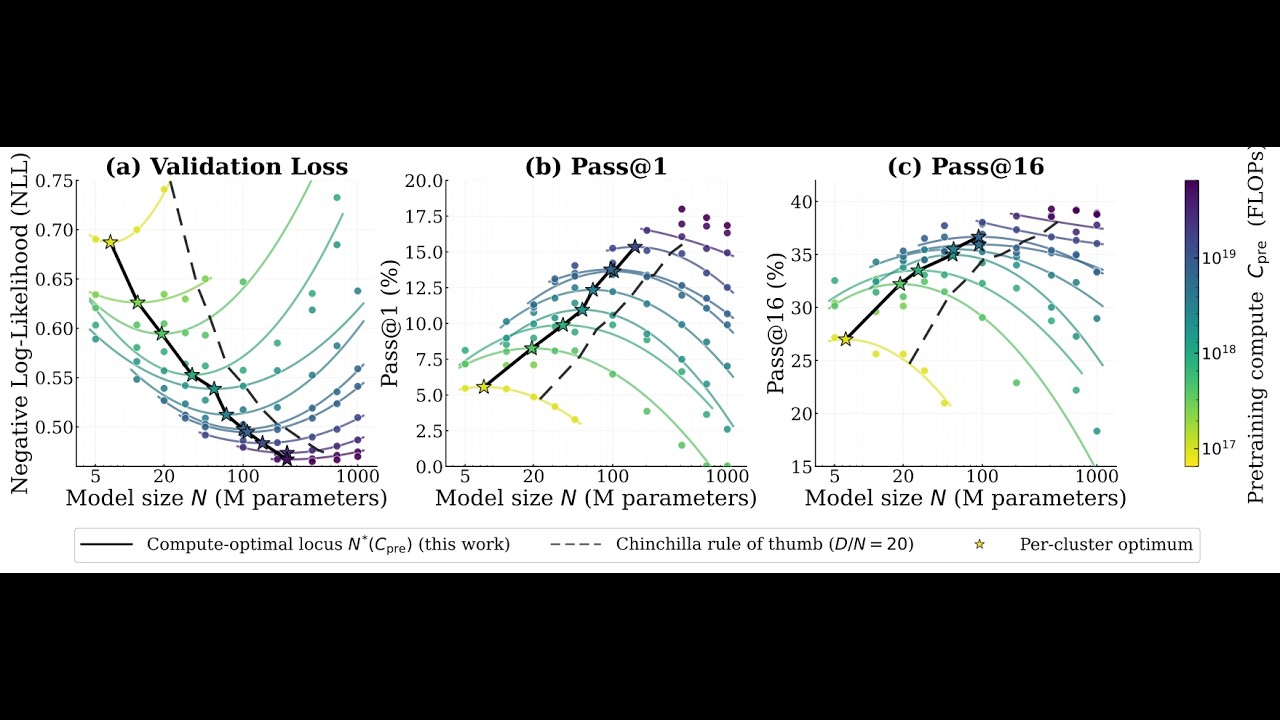
Hugging Face Journal Club: Scaling Laws for Pre-training & RL Aug 4, 2026 · 30:57 The research team discusses a joint scaling law for pre-training and RL, showing how compute allocation across these stages impacts downstream task performance. Key findings relate to optimizing model size versus training duration. Local Models: Trust, Control, Optimization — Carter Abdallah, NVIDIA Aug 7, 2026 · 43:21 Open models are key to building trust and sovereignty. By owning the full stack—from weights to training traces—developers can specialize AI for niche use cases, achieving performance that surpasses generalized frontier closed APIs. Hugging Face Journal Club: Direct On-Policy Distillation Aug 11, 2026 · 33:25 This paper proposes Direct On-Policy Distillation, a cheap way to transfer RL benefits from small models to large ones by using policy shifts as dense reward signals.

Recent signals

Is a Faster Model Actually Faster? Test the Whole Job — Morgan Suo, MiniMax Oct 21, 2026 · 17:43 A faster model only helps if the finished job gets faster. We test M3.1 Flash by measuring the total cost (time, compute, and manual fixes) of a complex research report, proving that speed must be balanced with accuracy and reliability. Training Cognition SWE-1.7: Asynchronous RL at Global Scale Oct 7, 2026 · 22:18 This talk covers the systems and algorithmic challenges behind making globally distributed RL work at scale. We will discuss how we decouple training from inference, propagate compressed weight updates across datacenters, and design the infrastructure to tolerate frequent hardware failures. What Makes Open Models Fast in Production — Sujee Maniyam, Nebius Oct 3, 2026 · 20:32 Running open LLMs in production requires managing the full loop: inference, data, post-training, and deployment. Nebius Token Factory provides a full-stack solution, optimizing performance using techniques like speculative decoding and KV cache offloading.

Browse view