How to Get Frontier Coding Results at 70% Lower Cost - Nouha Dziri, Cohere
Summary
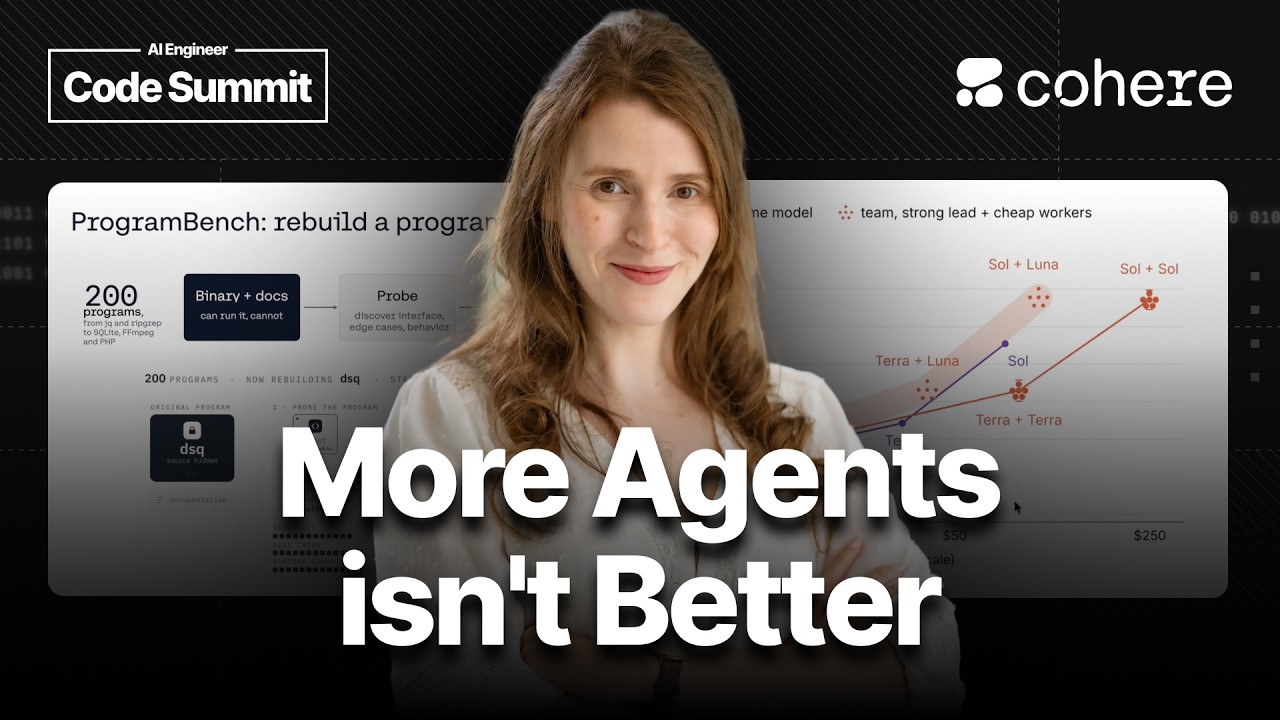
This presentation details methods for optimizing multi-agent coding teams to achieve 'frontier coding' results while drastically reducing computational costs. The core finding is that while teams of agents significantly outperform solo agents, the cost increase is substantial (4 to 7 times more). Optimization requires treating team design as a compute allocation problem, identifying the task's bottleneck stage (e.g., planning in ProgramBench), and strategically allocating more agents to that specific stage. Furthermore, using a strong lead model (e.g., Sol) combined with cheaper worker models (e.g., Luna) can achieve near-frontier performance at a fraction of the cost.
Key takeaways
-
Strategic Resource Allocation is Key
21:40
The performance gain is highly dependent on where agents are deployed. The extra agent pays off most in the task's bottleneck stage. For ProgramBench, the bottleneck was planning, meaning allocating more agents to planning provided significant performance gains at half the cost compared to the solo agent.
-
Lead Strength Sets the Ceiling, Workers Set the Price
25:40
The lead model dictates the upper bound of performance, while the worker models determine the cost. Using a strong lead (e.g., Sol) with cheaper workers (e.g., Luna) can achieve near-frontier results at a much lower cost.
-
Hierarchy Over Peer Communication
28:20
Agents tend to operate in a hierarchical manner, reporting primarily to the lead (84% of messages went from worker to lead). Direct peer-to-peer communication, while possible, was found to be largely ineffective or distracting, often acting as overhead.
More digests on Multi-Agent Systems
Technical details
-
Agent Team Architecture
700s
The multi-agent harness is designed as a top-down hierarchy with a lead agent that dynamically decides the team size and worker roles. Two lead types were tested: the 'blocking lead' (waits for all workers to report back) and the 'asynchronous lead' (continues working while workers report). The blocking lead was found to be more reliable for task completion.
-
Benchmarking and Metrics
1000s
Experiments were conducted on ProgramBench (a reverse engineering task starting from a binary executable) and Commit0. The key metric is 'efficiency,' defined as the reward gained per added dollar of inference compute, allowing researchers to pinpoint the most valuable stage (planning, implementation, or verification).
-
Scaling and Optimization
1100s
The team design was framed as a compute allocation problem. The study demonstrated that scaling agents in the planning stage provided the highest reward-to-cost ratio, suggesting that discovery and understanding the binary's behavior is the primary bottleneck.
Mentioned resources
- ProgramBench
- Commit0
- Cohere
Channel & topics
Watch on YouTube · Back to latest
This independent, AI-assisted summary is provided for commentary and informational purposes. It may contain errors or omit important context. Please watch the original video for the creator's complete presentation. Video, thumbnail, and related copyrights belong to their respective owners.