AI Eval Concepts Explained in 15 Minutes
Summary
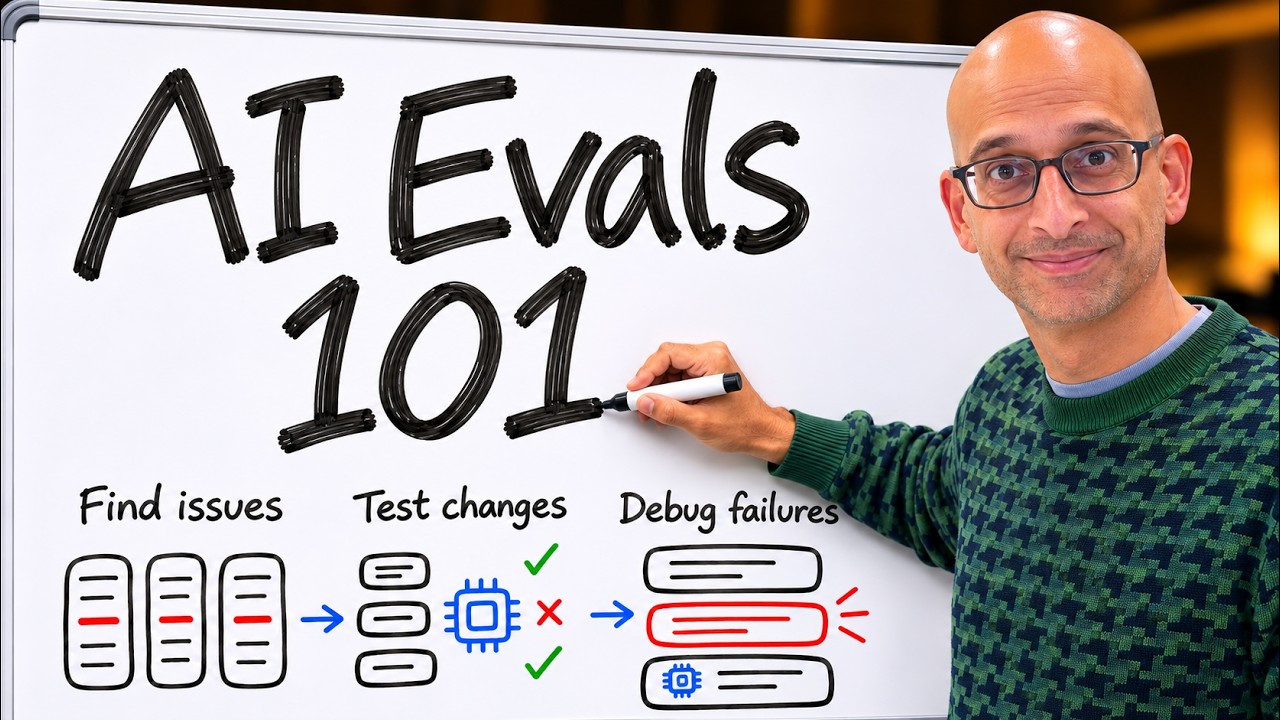
This guide provides a conceptual overview of AI evaluation (Evals), detailing the shift from general foundation model benchmarks (like MMLU) to highly specific, product-focused evals. Key methodologies include capturing comprehensive user session 'traces,' performing structured error analysis, and implementing automated grading systems using techniques like train/dev/test splits and LLM judges. The process emphasizes integrating these evals into CI/CD pipelines and using them as guard rails to ensure product reliability and guide iterative improvements.
Key takeaways
-
Product Evals vs. Foundation Benchmarks
Product-specific evals test performance on unique, task-critical workflows (e.g., order cancellation), whereas foundation model benchmarks test general intelligence (e.g., MMLU). Product evals often reveal a unique Pareto frontier due to task-specific constraints.
-
The Importance of Traces
0:02
A trace is a comprehensive record of an AI workflow, capturing all inputs, context, tool calls, and results. These traces are essential for debugging, testing changes, and identifying failure patterns.
-
Structured Error Analysis
0:03
Instead of random annotation, group failures into themes or taxonomies (e.g., 'false confirmations,' 'tool call failed'). Start analysis by simply counting failures within these defined groups to guide development efforts.
-
Automated Evals Setup
0:07
Automated evals grade traces using code assertions, classifiers, or LLMs as judges. It is highly recommended to use binary (pass/fail) scoring and to split the data into Train, Dev, and Test sets to prevent overfitting.
-
Deployment and Guardrails
0:12
Once validated, automated evals can be integrated into CI/CD pipelines, used to monitor production traffic in real-time, or implemented as 'guard rails' to block unsafe requests from reaching the user.
More digests on AI Evaluation (Evals)
Technical details
-
Traces and Workflow Capture
3s
A trace must capture every element of an AI interaction, including user prompts, system prompts, context, tool calls, tool call results, and sub-agent interactions. This requires instrumenting the code and storing the data in a viewable database.
-
Sampling Strategies
4s
To efficiently review traces, use sampling methods: 1) Random sampling (best for exploring 'unknown unknowns'); 2) Clustering (grouping similar themes); or 3) Data analysis (computing statistics like number of turns or latency to find outliers).
-
Synthetic Data Generation
4s
Synthetic data should generate plausible *inputs* (user messages or system inputs) to be run through the existing application logic, rather than generating entire traces. This is particularly useful for simulating edge cases (e.g., 'cancel order before shipping').
-
Automated Evaluation Methodology
7s
For robust automated evals, use a three-way data split: The **Train set** provides examples for the judge/model; the **Dev set** (approx. 40%) is used to tune the prompt and observe agreement between human and evaluator; and the **Test set** is held aside to confirm that the model has not overfit.
-
Evaluation Pitfalls
10s
Avoid using generic metrics (e.g., scores on a 1-5 range) as they are not actionable. Instead, measure specific, binary failures relevant to the product's core function. Evals should guide product decision-making, defining clear pass/fail thresholds.
Mentioned resources
Channel & topics
Watch on YouTube · Back to latest
This independent, AI-assisted summary is provided for commentary and informational purposes. It may contain errors or omit important context. Please watch the original video for the creator's complete presentation. Video, thumbnail, and related copyrights belong to their respective owners.