
Hugging Face Journal Club: Direct On-Policy Distillation
This paper proposes Direct On-Policy Distillation, a cheap way to transfer RL benefits from small models to large ones by using policy shifts as dense reward signals.
Read articleTopic
All digests tagged Reinforcement Learning (RL)
This paper proposes Direct On-Policy Distillation, a cheap way to transfer RL benefits from small models to large ones by using policy shifts as dense reward signals.
Read article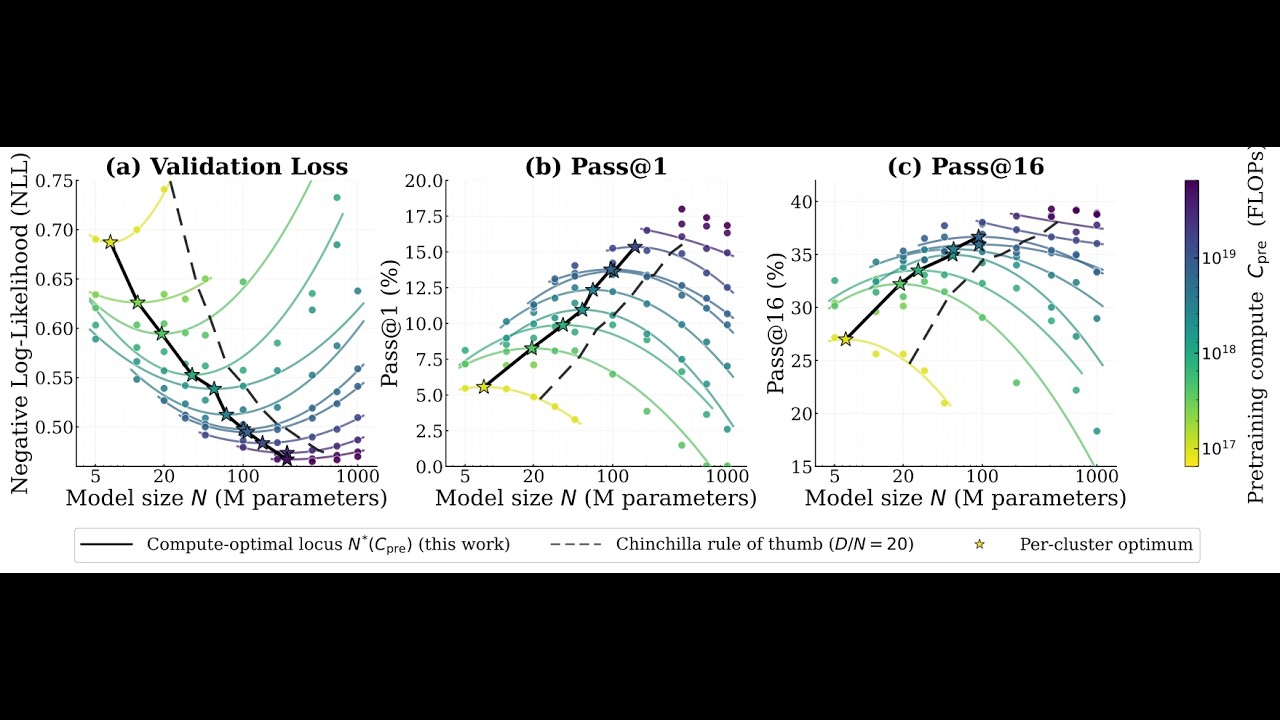
The research team discusses a joint scaling law for pre-training and RL, showing how compute allocation across these stages impacts downstream task performance. Key findings relate to optimizing model size versus training duration.
Read article
The lecture explores advanced LLM verification techniques, moving from simple outcome checks (GSM8K) to sophisticated process-based reward models (PRMs). Learn how ensembling weak verifiers can dramatically close the generation-verification gap.
Read article
Dive into train-time scaling and RL techniques that enable self-improving AI agents. Learn how STaR, DeepSeekMath, and DAPO boost reasoning in LLMs using closed feedback loops.
Read article
Learning on the job: The future of post-training involves teaching agents to continuously adapt in real-world enterprise harnesses. This requires moving beyond controlled synthetic environments to handle non-replayable, off-policy data.
Read article
Will Brown discusses extending Reinforcement Learning (RL) into complex, real-world tasks that lack clean, verifiable rewards. The core thesis is that 'environments' must serve as the anchor for learning.
Read article
MiniMax M3's open weights model requires complex infrastructure, including custom GPU kernels and advanced KV cache management, to support agentic and multimodal workloads at scale. The discussion covers the engineering challenges of 'day zero' deployment.
Read article
The course emphasizes understanding the mathematical foundations of ML, covering Supervised, Unsupervised, and Reinforcement Learning. A key focus is optimizing algorithms for hardware compatibility.
Read article
The talk details designing LLM coaches that promote user agency by eliciting qualitative context and navigating uncertainty. Techniques include zero-shot Bayesian Adaptive Planning.
Read article
Learn how Asynchronous On-Policy Distillation (AsyncOPD) boosts training throughput by 2-3x, overcoming GPU blocking in conventional distillation methods.
Read article
Lila Sciences is building scientific superintelligence by treating the wet lab as an RL verifier. The goal is to create a general reasoning model trained on 10 trillion experimentally-verified tokens across biology, chemistry, and materials.
Read article
Inkling is a massive, open-weight multimodal model with 1T parameters and 1M context window. It supports BF16/NVFP4 formats and integrates seamlessly with vLLM, SGLang, and llama.cpp for robust deployment.
Read article