Building a Commercial Submission Intake Workflow with LlamaParse
Summary
This webinar details an end-to-end commercial submission intake workflow designed to automate the processing of complex, multi-format documents (e.g., broker emails with various attachments). The system uses a layered approach, starting with document classification and splitting, followed by advanced parsing and extraction. Key components include LlamaParse for transforming documents into structured AI data, Extract for pulling specific values with bounding boxes and confidence scores, and Verify for detecting document manipulation. The workflow integrates deterministic checks, AI checks, and a human-in-the-loop review process, ultimately saving reconciled data into a data warehouse like Snowflake.
Key takeaways
-
Layered Document Processing Workflow
19:03
The system processes submissions by classifying, splitting, parsing, extracting, and verifying documents sequentially. This ensures that all data is captured and checked for integrity before reaching the decision layer.
-
Human-in-the-Loop Design
26:36
The application is designed so that human reviewers only need to focus on 'exceptions'—discrepancies flagged by the AI or deterministic checks (e.g., TIV mismatch, missing loss history). This significantly reduces manual review time.
-
Data Lineage and Traceability
21:40
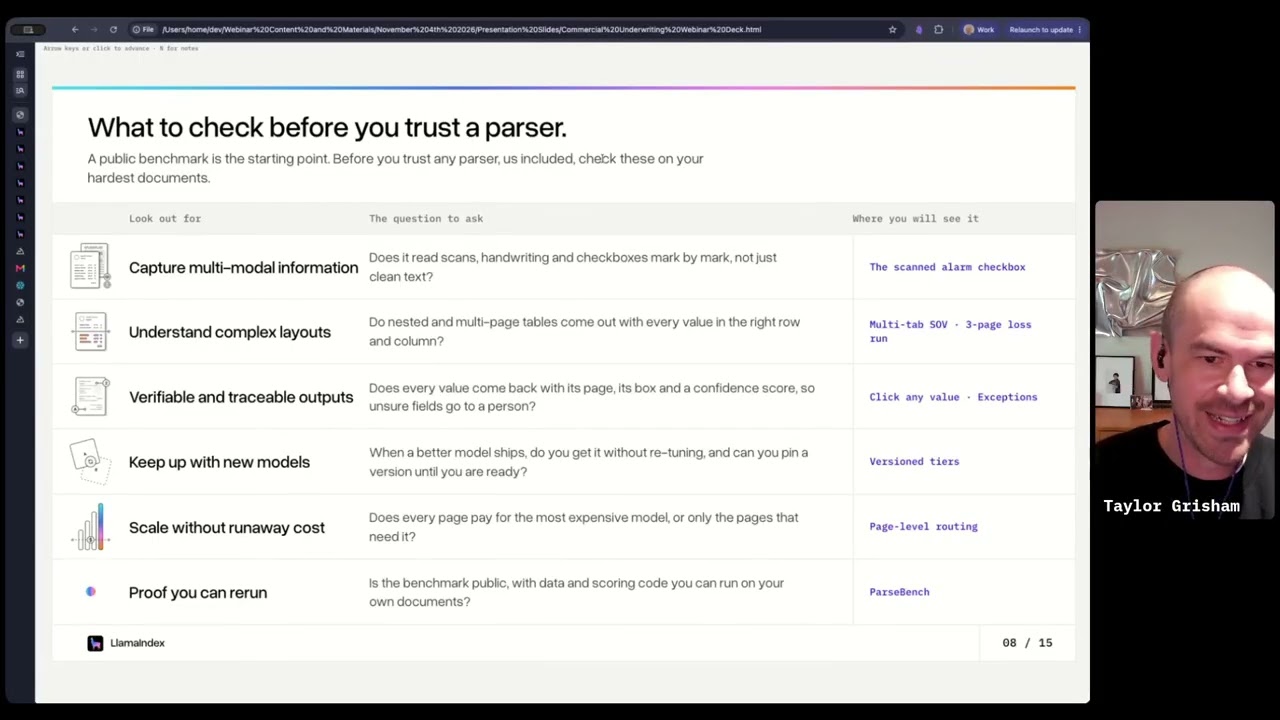
Both Parse and Extract provide bounding boxes and source information, allowing human reviewers to trace exactly where every piece of extracted data originated within the source document, which is critical for compliance and auditing.
-
Integration and Scalability
27:50
The workflow is designed to output reconciled data into external systems, such as Snowflake, and can be adapted to legacy systems lacking APIs via a Computer Use Agent (CUA) and an MCP (Multi-Channel Platform) interface.
Technical details
-
Document Parsing and Structuring
830s
LlamaParse takes over 130 file types and converts them into usable AI data. It outputs structured formats like Markdown, JSON, and text, and offers different tiers (e.g., Agentic Plus for degraded/complex documents, Fast Mode for simple text) to balance accuracy and cost.
-
Data Extraction (Extract)
930s
Unlike Parse (which captures the whole document), Extract pulls specific, targeted values based on a defined schema (which can be provided via JSON or an agent prompt). Outputs include the value, a bounding box, and a confidence score.
-
Document Verification (Verify)
1030s
The Verify solution analyzes documents to detect potential signs of manipulation or alteration, providing an extra layer of security and integrity checking.
-
Workflow Components
1210s
The workflow utilizes 'Split' (dividing a single document into multiple components, e.g., AORD 125 and ACORD 140) and 'Classify' (determining the document type, e.g., Loss Run, with a confidence score).
-
Multi-File Consolidation
2170s
When multiple documents mention the same fact (e.g., TIV), the system uses an extraction layer and subsequent logic to compare values across documents, flagging discrepancies for human review.
Mentioned resources
- ParseBench
- ExtractBench
- LlamaIndex Playground
- Snowflake
Channel & topics
Watch on YouTube · Back to latest
This independent, AI-assisted summary is provided for commentary and informational purposes. It may contain errors or omit important context. Please watch the original video for the creator's complete presentation. Video, thumbnail, and related copyrights belong to their respective owners.