78% Wanted This AI Feature. Almost Nobody Used It - Supriya Subudhi, Bumble
Summary
This talk details the complexities of A/B testing for Generative AI (GenAI) features, using the example of an AI photo feedback tool at Bumble. The core message is that a positive A/B test result is merely the starting point. Successful AI product deployment requires deep consideration of user adoption patterns, analyzing the 'long tail' of data rather than just averages, managing the escalating costs of advanced models, and ensuring global legal compliance.
Key takeaways
-
Openness does not predict usage
3:58
Users may express high interest in an AI feature (e.g., 78% wanting feedback), but actual adoption during A/B testing can be much lower (10-15%). To improve usage, the AI guidance must be baked into the user's existing workflow, not presented as a standalone feature. (2:38)
-
The average win hides the tail
8:39
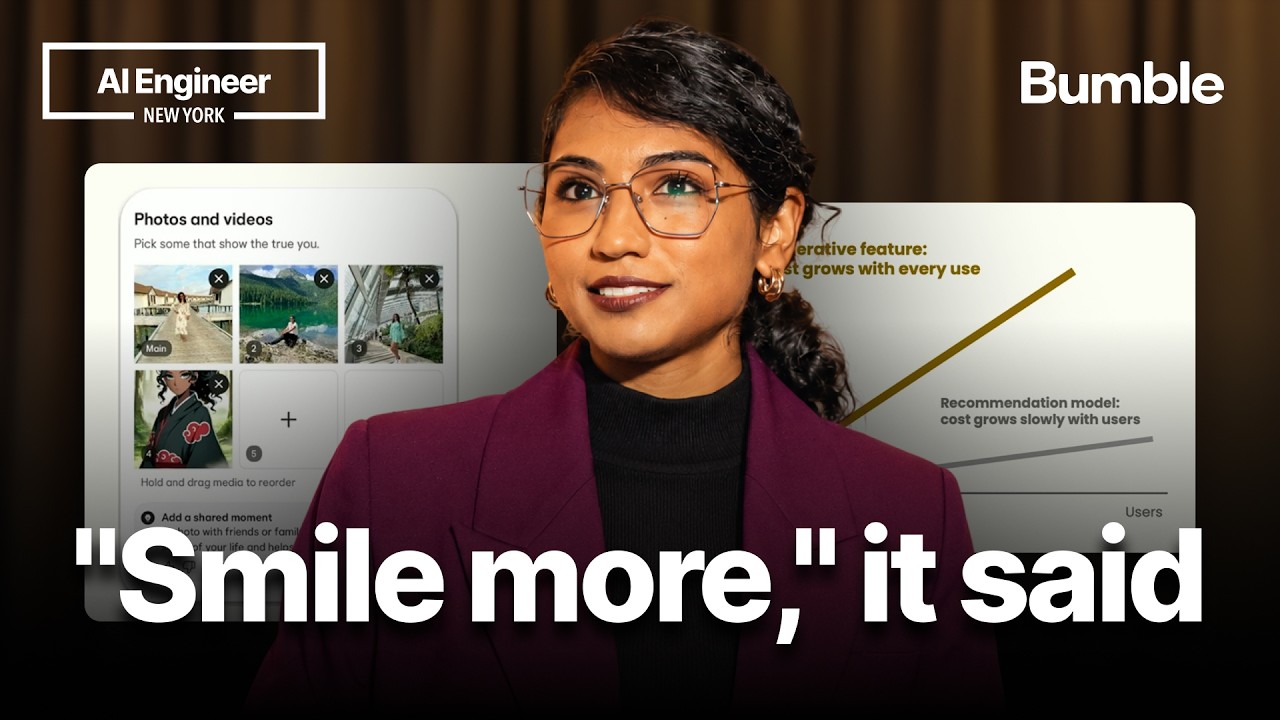
Relying solely on top-line metrics (the average win) is insufficient. Detailed analysis of the 'long tail' is necessary to identify issues, such as AI giving contradictory or unhelpful advice (e.g., telling already smiling people to smile more). (5:19)
-
Cost vs. Quality (Green Dashboard, Red Bill)
12:34
High-quality AI feedback often requires the best LLMs, which can be significantly more expensive (up to 10x). The cost of GenAI scales with usage, unlike traditional ML algorithms. It is critical to balance desired accuracy with scalability and budget. (7:54)
-
Global Rollout and Compliance
AI features must account for international regulations and legal risks. A feature successful in one market (e.g., the US) may not be deployable elsewhere, requiring product teams to plan for compliance early in the development cycle. (11:49)
Technical details
-
A/B Testing for AI
30s
A positive A/B test result only marks the beginning of the product journey. The evaluation must move beyond simple binary success/failure metrics. (0:30)
-
AI Guardrails and Safety
519s
When building AI features, strong guardrails must be set to prevent the model from suggesting changes that users cannot control (e.g., skin color, height). (5:19)
-
Evaluation (Evals)
630s
Setting up rigorous evaluation tools (evals) is critical for analyzing real user outputs, ensuring the prompt is effective, and validating the model's performance across different user segments (e.g., gender, language). (6:30)
-
LLM Cost Modeling
754s
Unlike traditional ML algorithms, the incremental cost of GenAI increases directly with usage. Product teams must understand if the AI use case is for short-term revenue boosts or long-term brand equity. (7:54)
Mentioned resources
Channel & topics
Watch on YouTube · Back to latest
This independent, AI-assisted summary is provided for commentary and informational purposes. It may contain errors or omit important context. Please watch the original video for the creator's complete presentation. Video, thumbnail, and related copyrights belong to their respective owners.